Choose the supervision before choosing the archive
A useful buying brief starts with the capability the model must demonstrate. Caption training asks for an image-to-description relationship. Referring-expression grounding asks the model to connect a phrase to a specific region or object. Visual question answering asks it to select or construct an answer supported by the input. Treating these as interchangeable can produce a collection with attractive totals and the wrong labels. An image tagged “kitchen” may support scene classification while supplying no description of a person’s activity or the location of a particular utensil.
The COCO task index separates captioning, detection, keypoints and other tasks. Visual Genome’s format documentation describes image-linked regions, phrases and question-answer objects. These are useful design references, not a claim that either benchmark’s files can be repackaged for every commercial use. In a procurement discussion, ask the supplier to show the actual record type and one complete linked example before accepting a category name.
Describe the image domain and the downstream failure
Photographs, screenshots, scans, diagrams and rendered scenes can all enter a multimodal pipeline, but their visual conventions differ. Write down whether the deployment input is a mobile photograph of a product, a dense shelf scene, an outdoor sign or an illustrated manual. Then identify the failure the source should help address: missed small objects, unsupported counting, confusion between similar products, poor reading of visible text or uncertain spatial relationships. This makes the specification more useful than requesting a broad “VLM dataset.”
For photographic material, define minimum useful detail after the model’s actual preprocessing. A high-resolution original may be reduced to a size at which a label, hand or small object is no longer distinguishable. Review the same resize, crop and compression path the model will encounter. Keep the original dimensions and preprocessing version in the manifest so a later investigation can determine whether an error came from the photograph, its transformation or the text label.
Keep descriptions grounded in observable evidence
A caption should distinguish what is visible from what is inferred. In a studio photograph, “two chairs beside a table” is observable; the identity of a future guest, the quality of the microphone signal and the commercial license state are not. Decide whether uncertain object names should use a broader term, whether relative position is camera-relative, and whether the task requires exhaustive descriptions or a small number of salient facts. There is no single best caption style for every training objective.
A review rubric can score object identity, count, attributes, relationships and unsupported additions separately. This helps avoid accepting a polished sentence that gets its central relationship wrong. Do not require one exact reference string when several faithful descriptions are valid. At the same time, allow reviewers to reject a paraphrase that subtly changes a count, negation or actor-object relationship. Preserve the proposed text, corrected text and rejection reason instead of silently overwriting the history.
A real photograph, with illustrative text variants
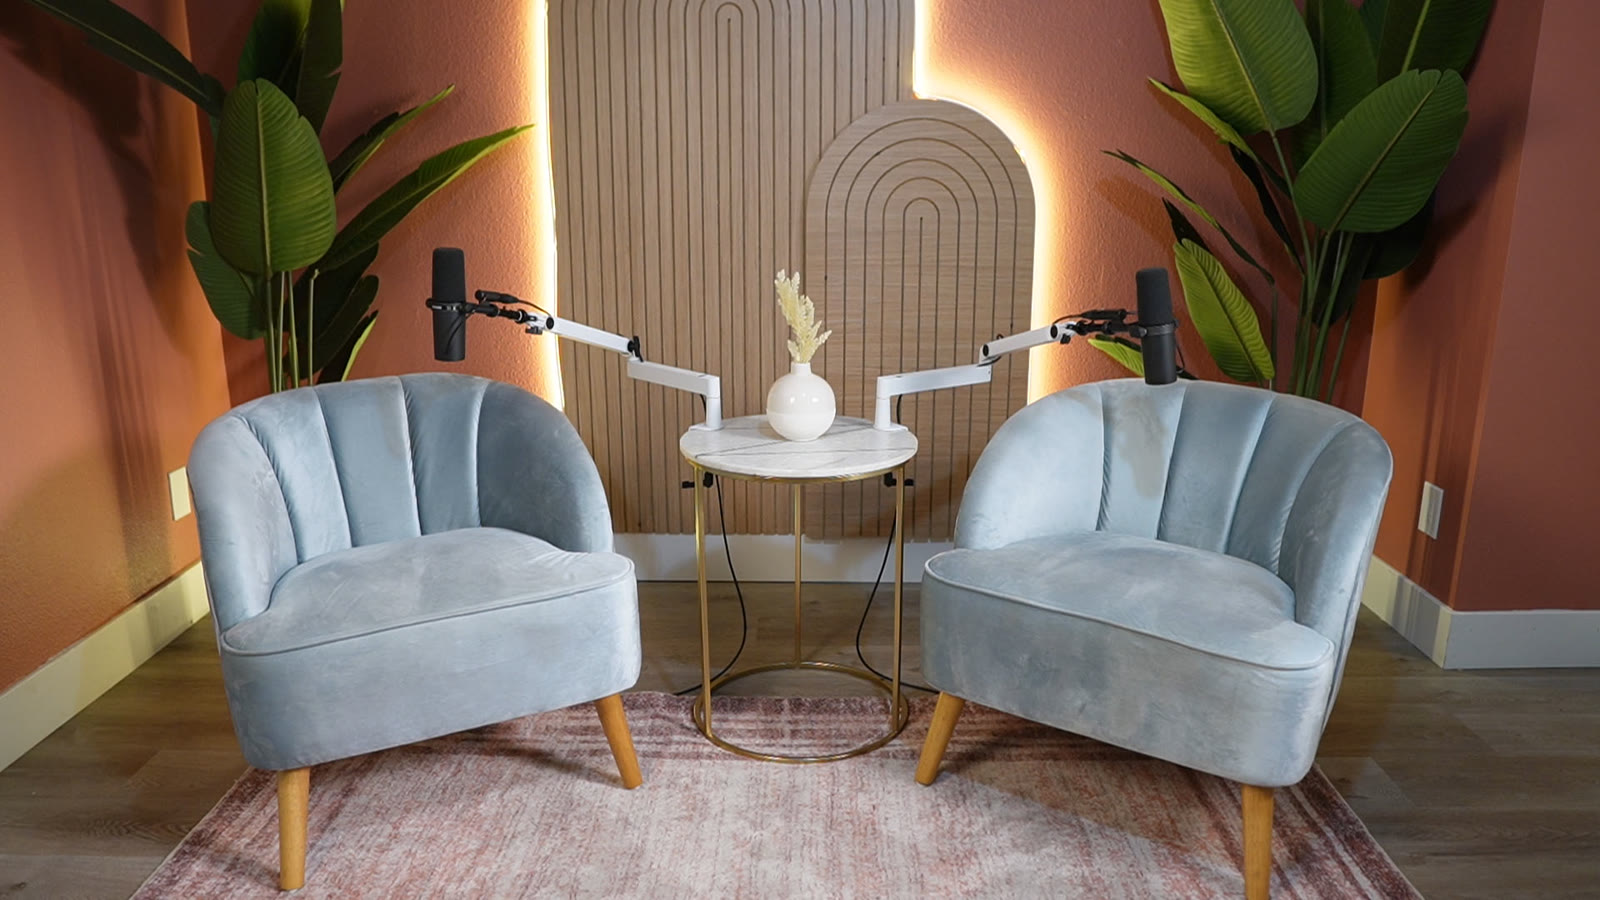
The photograph below comes from Fiund’s own studio context. It is shown to demonstrate a review method, not to advertise a cleared image-training collection. The descriptive variants are authored examples rather than independently adjudicated ground truth. A future dataset sample would need its own source review, annotation acceptance and agreed use.
A grounded variant is “Two light-blue chairs sit beside a round table with a white vase and two boom microphones.” A weaker variant is “A podcast studio,” which may be true but provides little detail for counting or spatial understanding. A rejected variant is “Three chairs surround a table,” because the displayed composition contains two chairs. The exercise shows why fluency, informativeness and factual correctness should receive separate attention. Download vlm-image-text-example.jsonl preserves the distinction between an editorial image, an illustrative label and an unestablished training-permission scope.
Region-level labels require coordinate and instance rules
A referring phrase such as “the microphone on the right” is only useful when the region points to the correct visible instance under an agreed coordinate convention. Specify whether rectangles use top-left plus width/height or two corners, whether values are pixels or normalized coordinates, and whether the image has already been rotated or cropped. Include the image dimensions against which a region was annotated. A valid JSON object with an incorrect reference frame is still an incorrect label.
Visual Genome’s readme provides a primary example of region descriptions carrying image references and coordinates. For a custom delivery, also define instance identity when objects overlap, when only part of an object is visible and when a phrase can legitimately refer to multiple objects. Request a small rendered overlay as well as raw coordinates during sample review. The overlay is a debugging view; the underlying annotation and its transformation history remain the durable record.
Separate source photographs, captions and permission evidence
The right to access a photograph, the origin of its caption and the permission to use either in a model are separate questions. An automatically generated description is not automatically a verified annotation. A caption copied from an unrelated web page may describe a different crop, a different edition or facts not visible in the file. Ask how text was produced, whether it was reviewed, and what source relationship connects it to the exact image delivered.
The public Shutterstock data-licensing page illustrates a commercial sourcing route spanning existing content and custom requirements. It does not establish a universal rate, a blanket permission for every asset or Fiund’s access to that content. Keep vendor statements attributed, request the proposed artifact and terms, and avoid treating a research dataset’s code license as the image license. Fiund’s sourcing discussion should identify the documentation needed for the selected source rather than promise that every possible category is already cleared.
Count scale without hiding duplication or leakage
Report unique source images separately from caption count, region count, question count and augmented views. Five captions attached to one photograph can provide useful linguistic variation, but they do not create five independent scenes. Near-duplicate crops and repeated product shots can inflate apparent coverage. Preserve source families, capture sessions and derivative groups so evaluation can hold related material together.
For visual question answering, inspect whether question templates reveal the answer distribution. A model may learn that a certain wording usually implies a particular object without looking carefully at the image. Include visually similar counterexamples and genuinely unanswerable cases when relevant. Hold out images and their dependent labels as a group. When a source overlaps an existing public benchmark or a team’s pretraining corpus, record the uncertainty rather than claiming a contamination-free test set without evidence.
Plan an acceptance pilot around distinct failure slices
Select a small review package that deliberately includes easy examples and the conditions most likely to matter at deployment: crowded scenes, small text, unusual viewpoints, partial visibility, similar-looking objects and culturally or geographically specific contexts. State how these slices were selected. A sample chosen only for attractive pictures or fluent descriptions will not reveal the correction burden of the full source.
For each proposed pair, check that the image opens, the reference resolves, the text is in the specified language and the label supports the stated task. Then review factual support and ambiguity. Record acceptance by error type and slice rather than presenting one unexplained accuracy figure. Define critical failures, correction scope and the role of a second reviewer before scaling. Thresholds should come from the actual application and pilot; this guide does not prescribe a universal pass percentage.
Compare commercial scopes and cost units
A comparable quote separates source access, selected image volume, text production, localization or translation, region annotation, review and delivery preparation. The accepted unit may be an image-caption pair, an image with all required region labels or a question-answer record. Ask whether pricing counts drafts, accepted records, revisions or multiple descriptions of the same image. A per-image number is misleading if one offer includes detailed grounding and another includes only a short caption.
No representative transaction sample reviewed for this guide establishes an average commercial VLM image-data price. Build a pilot estimate from stated quantities and actual measured preparation effort, then keep rights fees and review separate. If a provider publishes a price, retain its date, included scope and restrictions rather than generalizing it to the market. The practical next step with Fiund is a brief identifying the image domain, task, label structure, required coverage and representative acceptance evidence.
Questions buyers ask
Sources & research notes
Public documentation reviewed 2026-11-13. Provider descriptions and published terms are attributed below. Published facts are attributed to their sources. Worked files are labeled as illustrative or as an inspected editorial source; neither implies commercial dataset clearance.
- COCO task and dataset indexCOCO Consortium · Reviewed 2026-11-13
Primary public reference for the linked factual claim. Artifact-specific access and permissions must be checked; a reference is not a Fiund inventory listing.
- Visual Genome data-format readmeVisual Genome project · Reviewed 2026-11-13
Primary public reference for the linked factual claim. Artifact-specific access and permissions must be checked; a reference is not a Fiund inventory listing.
- Shutterstock data licensingShutterstock · Reviewed 2026-11-13
Primary public reference for the linked factual claim. Artifact-specific access and permissions must be checked; a reference is not a Fiund inventory listing.
- COCO reference API and annotation structureCOCO Consortium · Reviewed 2026-11-13
Primary public reference for the linked factual claim. Artifact-specific access and permissions must be checked; a reference is not a Fiund inventory listing.